再论String和HashMap源码分析
在阅读本文之前,建议读者优先阅读专栏内前面的文章。
目录
前言
本文主要补充介绍String类,并分析HashMap源码中的构成以及一个典型的方法。
一、字符串常量池:
我们先看一下下面这段代码:
public class Main {
    public static void main(String[] args) {
        String s1 = "hello";
        String s2 = "hello";
        String s3 = new String("hello");
        String s4 = new String("hello");
        System.out.println(s1 == s2);
        System.out.println(s1 == s3);
        System.out.println(s3 == s4);
    }
}
请读者先思考一下,这段代码运行后会有什么结果,并且可以与下面的代码对比一下看看是否是和结果相同:
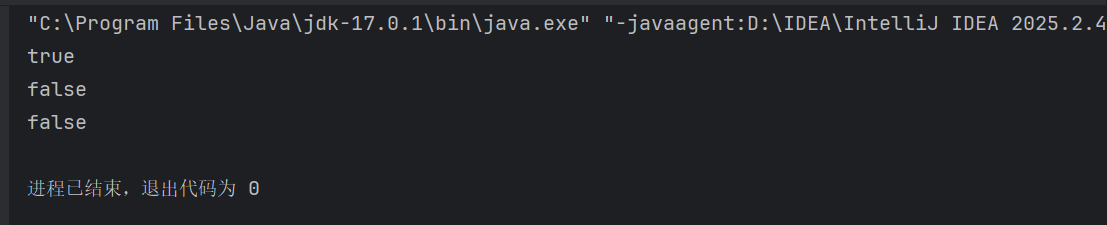
我们可以看到,上述程序创建方式类似,但是s1和s2引用的是一个对象,而s3和s4却不是。但这是为什么呢?在Java的程序中,字面类型的常量比如1、2、3、3.14、"hello"经常频繁使用,为了使程序的运行速度更快更省内存,Java为8种基本数据类型和String都提供了常量池。池是编程中一种非常常见且重要的提升效率的方式,之后我们也会遇到内存池、线程池、数据库连接池等概念。
为了节省存储空间以及程序的运行效率,Java中引入了下面这些。Class文件常量池,每个Java源文件编译后生成.Class文件中会保存当前类中的字面常量以及符号信息;运行时常量池,在.Class文件被加载时,.Class文件中的常量池也被加载到内存中称为运行时常量池,运行时常量池每个类都有一份;我们接下来要介绍的字符串常量池。这里这些我们都简单了解一下即可,后续在讲JVM时再详细阐释。
字符串常量池在JVM中是StringTable类,实际上是一个大小固定的HashTable,不同JDK版本下的字符串常量池的位置以及默认大小是不同的:
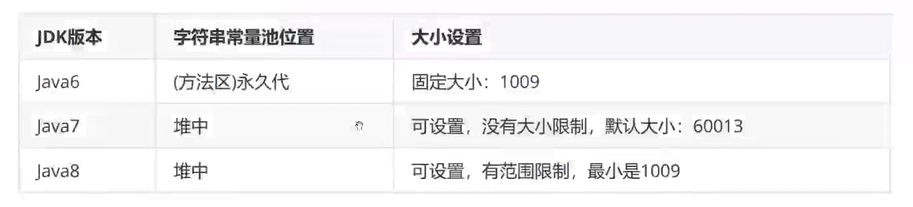
关于方法区、堆等内存结构的具体局部,后续JVM再详细介绍。由于不同的JDK版本对字符串常量池的处理方式不同,此处我们在Java8 HotSpot上分析。我们先来看看直接使用字符串常量进行赋值,我们先用下面这个代码:
public class Main {
    public static void main(String[] args) {
        String s1 = "hello";
        String s2 = "hello";
        String s3 = new String("world");
        String s4 = new String("world");
    }
}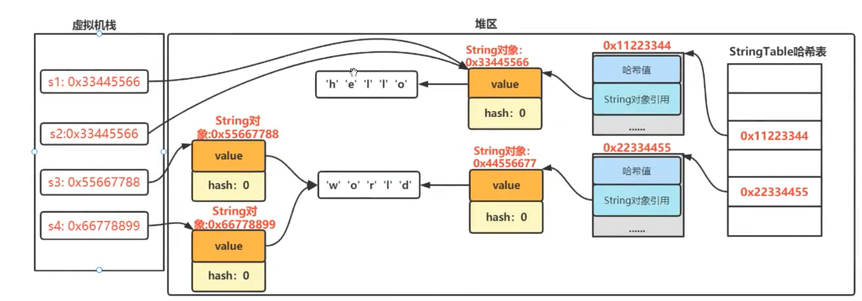
这几行代码执行后,字符串对象在虚拟机栈、堆以及字符串常量池中的引用关系就是上图这样。左侧是虚拟机栈中的局部变量表,s1、s2、s3、s4本质上保存的都是对象引用地址,而不是真正的字符串内容。对于s1 = "hello" 和 s2 = "hello"来说,字符串字面量"hello"会先进入字符串常量池,第一次使用时会在堆中创建对应的String对象,并在StringTable中保存它的引用;第二次再使用"hello"时,JVM发现常量池中已经存在该字符串对象,就不会重新创建,而是直接让s2复用s1指向的那个对象,因此图中s1和s2保存的是同一个地址。
对于s3 = new String("world")和s4 = new String("world")来说,"world"作为字符串字面量也会先进入字符串常量池,StringTable中保存的是常量池中"world"对象的引用;但是由于代码中使用了 new String("world"),所以每执行一次new,都会在堆中额外创建一个新的String对象。因此图中s3和s4分别指向两个不同的堆对象,它们的对象地址不同,但它们内部的value都指向同一份表示"world"的底层字符内容。也就是说,字面量方式创建的字符串会尽量复用字符串常量池中的对象,而new String()会强制在堆中创建新的String对象;所以s1 == s2为true,而s3 == s4为false,但s3.equals(s4)为true。这张图的核心就是说明变量保存的是引用,字符串常量池负责复用字面量对象,而new String()会产生新的堆对象。
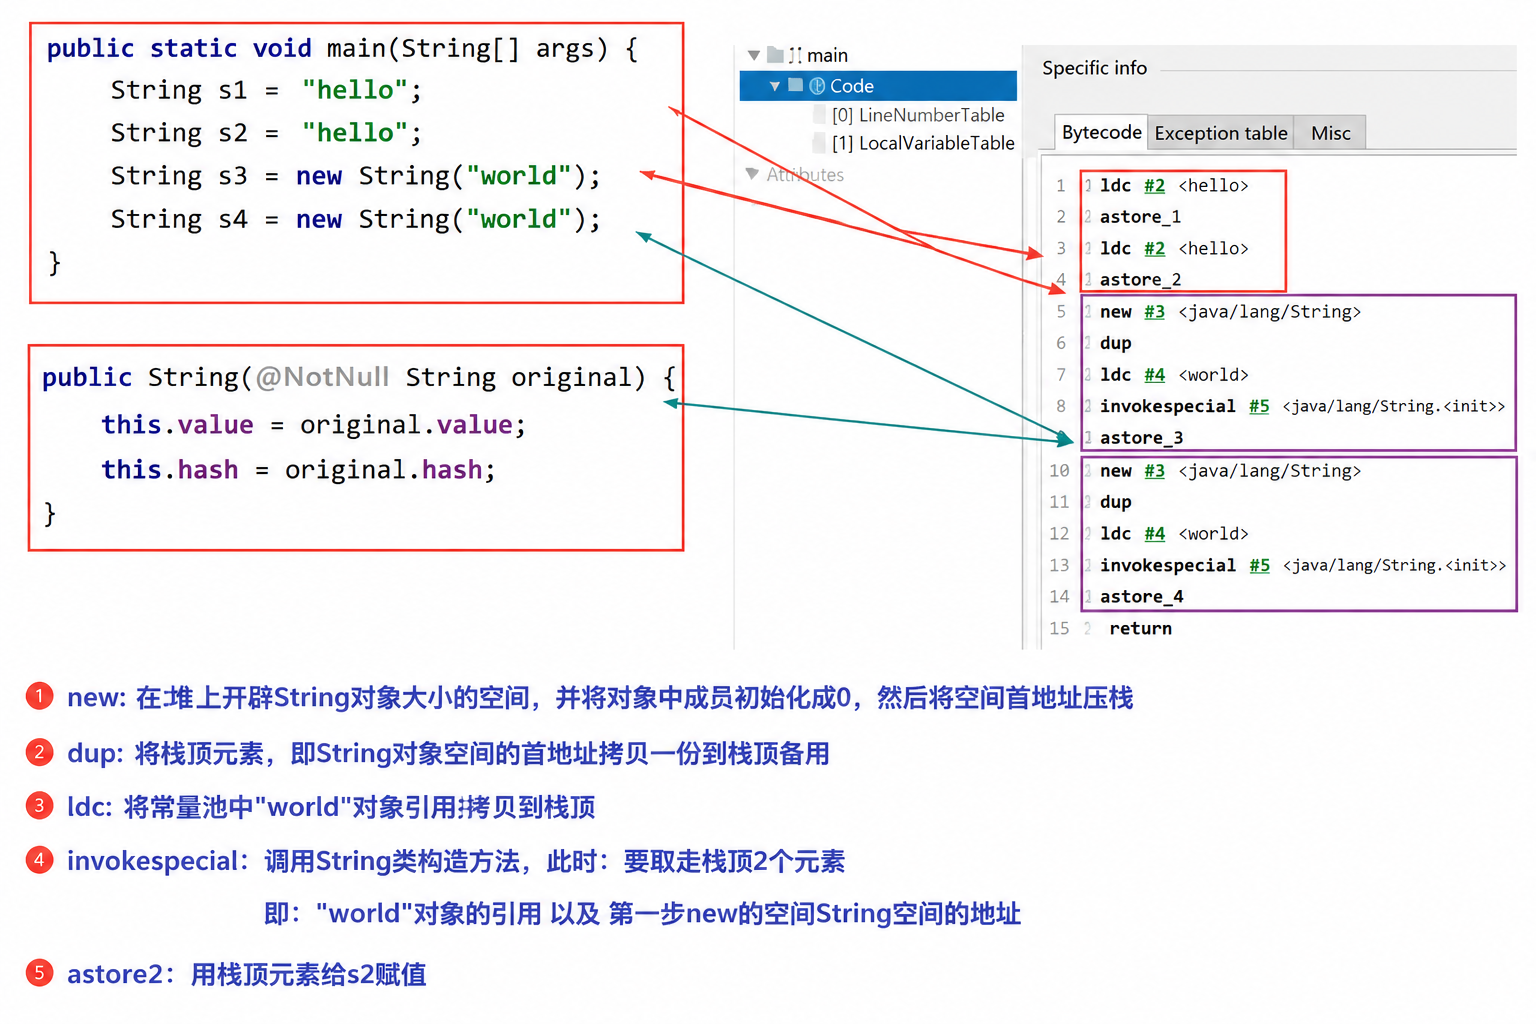
接下来我们来说下intern方法,这是一个native方法。native方法指的就是底层使用C++实现,看不到实现的源代码的方法。这个方法的作用就是手动将创建的String对象添加到常量池中。比如说我们有如下的代码:
public class Main {
    public static void main(String[] args) {
        char[] ch = new char[]{'a', 'b', 'c'};
        String s1 = new String(ch);
        String s2 = "abc";
        System.out.println(s1 == s2);
    }
}
其运行结果如下:
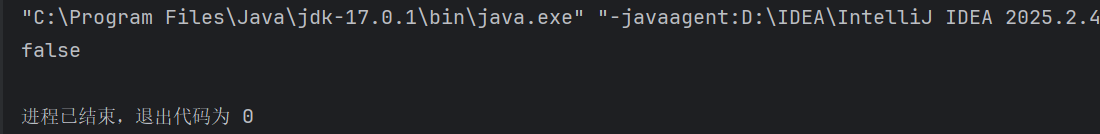
但如果说我们略作改动为如下的代码,结果就会发生变化:
public class Main {
    public static void main(String[] args) {
        char[] ch = new char[]{'a', 'b', 'c'};
        String s1 = new String(ch);
        s1.intern();
        String s2 = "abc";
        System.out.println(s1 == s2);
    }
}
其运行结果如下:
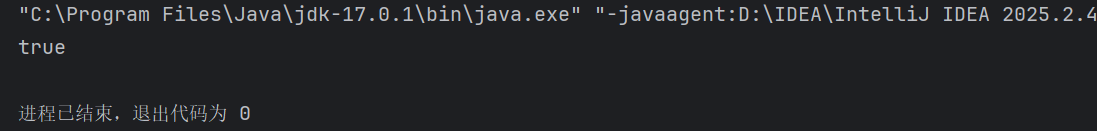
需要注意的是,在Java6和Java7、Java8中intern的实现是略有不同的。
二、HashMap源码补充分析:
我们这里需要先提前切换为Java8,因为之前其实一直在用Java17。
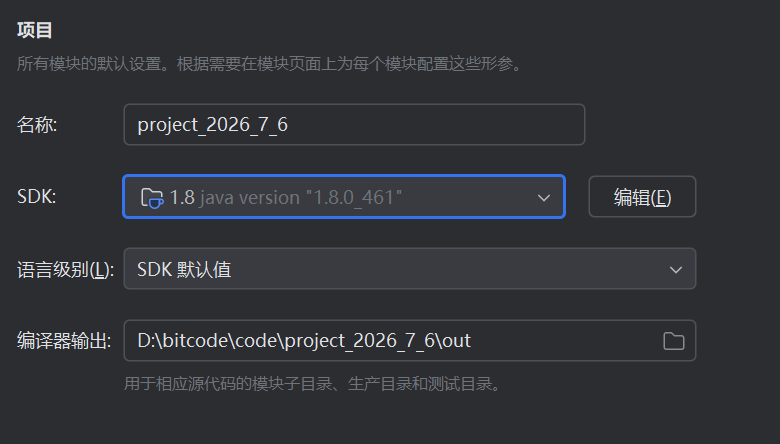
我们象征性写一下代码:
import java.util.HashMap;

public class Main {
    public static void main(String[] args) {
        HashMap<String, Integer> map = new HashMap<>();
        map.put("abc", 3);
    }
}
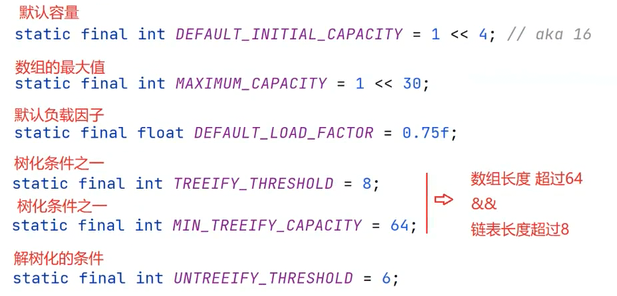
然后点进HashMap看一下它的源码,首先要来看一下它如下的成员变量。
    /**
     * The default initial capacity - MUST be a power of two.
     */
    static final int DEFAULT_INITIAL_CAPACITY = 1 << 4; // aka 16

    /**
     * The maximum capacity, used if a higher value is implicitly specified
     * by either of the constructors with arguments.
     * MUST be a power of two <= 1<<30.
     */
    static final int MAXIMUM_CAPACITY = 1 << 30;

    /**
     * The load factor used when none specified in constructor.
     */
    static final float DEFAULT_LOAD_FACTOR = 0.75f;

    /**
     * The bin count threshold for using a tree rather than list for a
     * bin.  Bins are converted to trees when adding an element to a
     * bin with at least this many nodes. The value must be greater
     * than 2 and should be at least 8 to mesh with assumptions in
     * tree removal about conversion back to plain bins upon
     * shrinkage.
     */
    static final int TREEIFY_THRESHOLD = 8;

    /**
     * The bin count threshold for untreeifying a (split) bin during a
     * resize operation. Should be less than TREEIFY_THRESHOLD, and at
     * most 6 to mesh with shrinkage detection under removal.
     */
    static final int UNTREEIFY_THRESHOLD = 6;

    /**
     * The smallest table capacity for which bins may be treeified.
     * (Otherwise the table is resized if too many nodes in a bin.)
     * Should be at least 4 * TREEIFY_THRESHOLD to avoid conflicts
     * between resizing and treeification thresholds.
     */
    static final int MIN_TREEIFY_CAPACITY = 64;
这些成员变量定义的是HashMap底层数组扩容、负载控制以及链表和红黑树转换的关键规则。DEFAULT_INITIAL_CAPACITY = 1 << 4表示默认初始容量为16,并且容量必须是 2 的幂,这样可以通过(n - 1) & hash快速计算元素下标,提高取模效率;MAXIMUM_CAPACITY = 1 << 30表示HashMap允许的最大容量,防止数组过大导致内存问题;DEFAULT_LOAD_FACTOR = 0.75f是默认负载因子,当元素个数超过容量 × 负载因子时就会触发扩容,例如默认容量16时,阈值就是12。TREEIFY_THRESHOLD = 8表示当某个桶中的链表节点数量达到8左右时,HashMap会尝试将链表转换为红黑树,以减少哈希冲突严重时的查询成本;UNTREEIFY_THRESHOLD = 6表示在扩容或拆分过程中,如果树中节点数量减少到6及以下,就会退化回普通链表,避免节点太少时维护红黑树反而浪费性能;MIN_TREEIFY_CAPACITY = 64表示只有当底层数组容量至少达到64 时,桶中的链表才允许树化,否则即使链表长度达到8,也会优先选择扩容而不是树化。整体来看,这些常量体现了HashMap的设计思想:正常情况下用数组加链表保证简单高效,冲突严重时用红黑树优化查询,而在容量较小时优先扩容来分散冲突。
然后是它的Node的定义:
    /**
     * Basic hash bin node, used for most entries.  (See below for
     * TreeNode subclass, and in LinkedHashMap for its Entry subclass.)
     */
    static class Node<K,V> implements Map.Entry<K,V> {
        final int hash;
        final K key;
        V value;
        Node<K,V> next;

        Node(int hash, K key, V value, Node<K,V> next) {
            this.hash = hash;
            this.key = key;
            this.value = value;
            this.next = next;
        }

        public final K getKey()        { return key; }
        public final V getValue()      { return value; }
        public final String toString() { return key + "=" + value; }

        public final int hashCode() {
            return Objects.hashCode(key) ^ Objects.hashCode(value);
        }

        public final V setValue(V newValue) {
            V oldValue = value;
            value = newValue;
            return oldValue;
        }

        public final boolean equals(Object o) {
            if (o == this)
                return true;
            if (o instanceof Map.Entry) {
                Map.Entry<?,?> e = (Map.Entry<?,?>)o;
                if (Objects.equals(key, e.getKey()) &&
                    Objects.equals(value, e.getValue()))
                    return true;
            }
            return false;
        }
    }
我们可以看到这段代码定义的是HashMap中最基础的节点结构Node<K,V>,它实现了Map.Entry<K,V>接口,用来保存一个键值对。每个Node中包含四个核心成员,hash表示key经过扰动计算后的哈希值,用于定位数组下标和比较节点;key保存键,因为HashMap中键一旦确定后不应该随意改变,所以被final修饰;value保存对应的值,允许通过setValue() 法修改;next指向同一个桶中的下一个节点,用来形成链表结构。也就是说,当多个key经过哈希计算后落到同一个数组位置时,这些键值对就会通过next串成一条链表。构造方法负责初始化一个节点的哈希值、键、值以及后继节点。
接下来是它的四个构造方法:
    /**
     * Constructs an empty <tt>HashMap</tt> with the specified initial
     * capacity and load factor.
     *
     * @param  initialCapacity the initial capacity
     * @param  loadFactor      the load factor
     * @throws IllegalArgumentException if the initial capacity is negative
     *         or the load factor is nonpositive
     */
    public HashMap(int initialCapacity, float loadFactor) {
        if (initialCapacity < 0)
            throw new IllegalArgumentException("Illegal initial capacity: " +
                                               initialCapacity);
        if (initialCapacity > MAXIMUM_CAPACITY)
            initialCapacity = MAXIMUM_CAPACITY;
        if (loadFactor <= 0 || Float.isNaN(loadFactor))
            throw new IllegalArgumentException("Illegal load factor: " +
                                               loadFactor);
        this.loadFactor = loadFactor;
        this.threshold = tableSizeFor(initialCapacity);
    }

    /**
     * Constructs an empty <tt>HashMap</tt> with the specified initial
     * capacity and the default load factor (0.75).
     *
     * @param  initialCapacity the initial capacity.
     * @throws IllegalArgumentException if the initial capacity is negative.
     */
    public HashMap(int initialCapacity) {
        this(initialCapacity, DEFAULT_LOAD_FACTOR);
    }

    /**
     * Constructs an empty <tt>HashMap</tt> with the default initial capacity
     * (16) and the default load factor (0.75).
     */
    public HashMap() {
        this.loadFactor = DEFAULT_LOAD_FACTOR; // all other fields defaulted
    }

    /**
     * Constructs a new <tt>HashMap</tt> with the same mappings as the
     * specified <tt>Map</tt>.  The <tt>HashMap</tt> is created with
     * default load factor (0.75) and an initial capacity sufficient to
     * hold the mappings in the specified <tt>Map</tt>.
     *
     * @param   m the map whose mappings are to be placed in this map
     * @throws  NullPointerException if the specified map is null
     */
    public HashMap(Map<? extends K, ? extends V> m) {
        this.loadFactor = DEFAULT_LOAD_FACTOR;
        putMapEntries(m, false);
    }
第一个HashMap(int initialCapacity, float loadFactor)是最完整的构造方法,可以同时指定初始容量和负载因子。它会先检查initialCapacity是否小于0,如果小于0就抛出异常;如果初始容量超过MAXIMUM_CAPACITY,就把它限制为最大容量;然后检查loadFactor是否小于等于0或者是否是非法数字NaN,如果不合法也会抛出异常。检查通过后,会把传入的负载因子保存到this.loadFactor中,并通过tableSizeFor(initialCapacity)把传入的容量调整成一个大于等于它的2的幂,然后暂时保存到threshold中。其实现如下:
    /**
     * Returns a power of two size for the given target capacity.
     */
    static final int tableSizeFor(int cap) {
        int n = cap - 1;
        n |= n >>> 1;
        n |= n >>> 2;
        n |= n >>> 4;
        n |= n >>> 8;
        n |= n >>> 16;
        return (n < 0) ? 1 : (n >= MAXIMUM_CAPACITY) ? MAXIMUM_CAPACITY : n + 1;
    }
这里要注意,JDK8中HashMap的底层数组不是在构造方法里立刻创建的,而是等第一次put时才真正初始化。
第二个HashMap(int initialCapacity)只允许指定初始容量,不指定负载因子,所以它内部直接调用第一个构造方法,也就是说,如果只传入容量,那么负载因子默认就是0.75。例如new HashMap<>(20),它会把初始容量20交给tableSizeFor处理,最终调整成32,因为HashMap的容量要求是2的幂。
第三个无参构造方法HashMap()是最常用的写法,它只设置了默认负载因子0.75,并没有立刻创建长度为16的数组。注释中说默认初始容量是16,意思是当第一次插入元素时,底层数组会按照默认容量16来初始化。所以无参构造创建出来的HashMap一开始只是一个空壳,真正的数组空间会延迟到第一次put时分配。
第四个HashMap(Map<? extends K, ? extends V> m)用来根据已有的Map创建一个新的HashMap。它先设置默认负载因子0.75,然后调用putMapEntries(m, false),把传入Map中的所有键值对复制到当前HashMap中。这个构造方法会根据原Map的元素数量计算一个合适的容量,尽量避免复制过程中频繁扩容。如果传入的Map是null,则会抛出NullPointerException。
接下来我们就可以看下put方法的源码:
    /**
     * Associates the specified value with the specified key in this map.
     * If the map previously contained a mapping for the key, the old
     * value is replaced.
     *
     * @param key key with which the specified value is to be associated
     * @param value value to be associated with the specified key
     * @return the previous value associated with <tt>key</tt>, or
     *         <tt>null</tt> if there was no mapping for <tt>key</tt>.
     *         (A <tt>null</tt> return can also indicate that the map
     *         previously associated <tt>null</tt> with <tt>key</tt>.)
     */
    public V put(K key, V value) {
        return putVal(hash(key), key, value, false, true);
    }
我们可以看到它实际上是返回了调用putVal方法的结果,在看这个代码之前,我们先来看一下它的第一个参数,也就是hash(key)。我们先看看这个hash方法:
    /**
     * Computes key.hashCode() and spreads (XORs) higher bits of hash
     * to lower.  Because the table uses power-of-two masking, sets of
     * hashes that vary only in bits above the current mask will
     * always collide. (Among known examples are sets of Float keys
     * holding consecutive whole numbers in small tables.)  So we
     * apply a transform that spreads the impact of higher bits
     * downward. There is a tradeoff between speed, utility, and
     * quality of bit-spreading. Because many common sets of hashes
     * are already reasonably distributed (so don't benefit from
     * spreading), and because we use trees to handle large sets of
     * collisions in bins, we just XOR some shifted bits in the
     * cheapest possible way to reduce systematic lossage, as well as
     * to incorporate impact of the highest bits that would otherwise
     * never be used in index calculations because of table bounds.
     */
    static final int hash(Object key) {
        int h;
        return (key == null) ? 0 : (h = key.hashCode()) ^ (h >>> 16);
    }
这个里面主要是后面那个有点抽象,我调用键值的哈希值去和它本身右移16位的结果去异或。这么做的目的很简单,就是为了实现让最后的结果分布更加均匀。接下来我们就可以看看putVal方法:
    final V putVal(int hash, K key, V value, boolean onlyIfAbsent,
                   boolean evict) {
        Node<K,V>[] tab; Node<K,V> p; int n, i;
        if ((tab = table) == null || (n = tab.length) == 0)
            n = (tab = resize()).length;
        if ((p = tab[i = (n - 1) & hash]) == null)
            tab[i] = newNode(hash, key, value, null);
        else {
            Node<K,V> e; K k;
            if (p.hash == hash &&
                ((k = p.key) == key || (key != null && key.equals(k))))
                e = p;
            else if (p instanceof TreeNode)
                e = ((TreeNode<K,V>)p).putTreeVal(this, tab, hash, key, value);
            else {
                for (int binCount = 0; ; ++binCount) {
                    if ((e = p.next) == null) {
                        p.next = newNode(hash, key, value, null);
                        if (binCount >= TREEIFY_THRESHOLD - 1) // -1 for 1st
                            treeifyBin(tab, hash);
                        break;
                    }
                    if (e.hash == hash &&
                        ((k = e.key) == key || (key != null && key.equals(k))))
                        break;
                    p = e;
                }
            }
            if (e != null) { // existing mapping for key
                V oldValue = e.value;
                if (!onlyIfAbsent || oldValue == null)
                    e.value = value;
                afterNodeAccess(e);
                return oldValue;
            }
        }
        ++modCount;
        if (++size > threshold)
            resize();
        afterNodeInsertion(evict);
        return null;
    }
这个方法相对复杂,所以我们一步一步慢慢来看。当我们第一次使用这个方法的时候我们会首先执行下面这段代码:
if ((tab = table) == null || (n = tab.length) == 0)
    n = (tab = resize()).length;
这一步体现了HashMap的懒加载机制。创建HashMap对象时,底层数组table通常还没有真正初始化,只有第一次插入元素时才会调用resize()创建数组。那我们这时候就需要看一下resize方法是如何定义的:
    /**
     * Initializes or doubles table size.  If null, allocates in
     * accord with initial capacity target held in field threshold.
     * Otherwise, because we are using power-of-two expansion, the
     * elements from each bin must either stay at same index, or move
     * with a power of two offset in the new table.
     *
     * @return the table
     */
    final Node<K,V>[] resize() {
        Node<K,V>[] oldTab = table;
        int oldCap = (oldTab == null) ? 0 : oldTab.length;
        int oldThr = threshold;
        int newCap, newThr = 0;
        if (oldCap > 0) {
            if (oldCap >= MAXIMUM_CAPACITY) {
                threshold = Integer.MAX_VALUE;
                return oldTab;
            }
            else if ((newCap = oldCap << 1) < MAXIMUM_CAPACITY &&
                     oldCap >= DEFAULT_INITIAL_CAPACITY)
                newThr = oldThr << 1; // double threshold
        }
        else if (oldThr > 0) // initial capacity was placed in threshold
            newCap = oldThr;
        else {               // zero initial threshold signifies using defaults
            newCap = DEFAULT_INITIAL_CAPACITY;
            newThr = (int)(DEFAULT_LOAD_FACTOR * DEFAULT_INITIAL_CAPACITY);
        }
        if (newThr == 0) {
            float ft = (float)newCap * loadFactor;
            newThr = (newCap < MAXIMUM_CAPACITY && ft < (float)MAXIMUM_CAPACITY ?
                      (int)ft : Integer.MAX_VALUE);
        }
        threshold = newThr;
        @SuppressWarnings({"rawtypes","unchecked"})
        Node<K,V>[] newTab = (Node<K,V>[])new Node[newCap];
        table = newTab;
        if (oldTab != null) {
            for (int j = 0; j < oldCap; ++j) {
                Node<K,V> e;
                if ((e = oldTab[j]) != null) {
                    oldTab[j] = null;
                    if (e.next == null)
                        newTab[e.hash & (newCap - 1)] = e;
                    else if (e instanceof TreeNode)
                        ((TreeNode<K,V>)e).split(this, newTab, j, oldCap);
                    else { // preserve order
                        Node<K,V> loHead = null, loTail = null;
                        Node<K,V> hiHead = null, hiTail = null;
                        Node<K,V> next;
                        do {
                            next = e.next;
                            if ((e.hash & oldCap) == 0) {
                                if (loTail == null)
                                    loHead = e;
                                else
                                    loTail.next = e;
                                loTail = e;
                            }
                            else {
                                if (hiTail == null)
                                    hiHead = e;
                                else
                                    hiTail.next = e;
                                hiTail = e;
                            }
                        } while ((e = next) != null);
                        if (loTail != null) {
                            loTail.next = null;
                            newTab[j] = loHead;
                        }
                        if (hiTail != null) {
                            hiTail.next = null;
                            newTab[j + oldCap] = hiHead;
                        }
                    }
                }
            }
        }
        return newTab;
    }
这个代码乍一看十分复杂,但实际上想干的事情很简单。我们首先会根据我们的table得到oldCap和oldThr的值,因为我们刚开始table为空,所以导致这两个整型值也都为0.然后我们走入下面的判断语句,会直接进入最后一个else的情况。这时根据我们最前面定义的常量会进行赋值,得到了newCap和newThr,进而得到newTab。所以在调用无参构造方法时,第一次put时会初始化出长度为16的数组。而后面的一长串的判断都是在对原来的哈希表中的元素进行重新哈希的过程,在我们这个过程就直接跳过,直接返回了得到的数组。所以我们此时就得到了第一个结论,当调用不带参数的构造方法的时候,第一次put会分配内存,并且大小为16。
我们接着往下走。接下来我们会进行如下的判断:
if ((p = tab[i = (n - 1) & hash]) == null)
    tab[i] = newNode(hash, key, value, null);
我们此时会通过对i的定义计算当前key应该放到数组的哪个位置。因为HashMap的数组长度始终是2的幂,所以可以用位运算代替取模运算,提高效率。如果计算出来的桶位置为空,也就是没有发生哈希冲突,那么直接创建一个新的Node放进去即可。如果该桶位置已经有节点,就会进入else分支,说明发生了哈希冲突。接下来先判断桶中第一个节点是不是和当前要插入的key相同:
if (p.hash == hash &&
    ((k = p.key) == key || (key != null && key.equals(k))))
    e = p;
判断key是否相同需要两个条件,第一,hash值相同;第二,key的引用相同,或者通过equals()判断相同。如果相同,说明这次插入的key已经存在,不需要新增节点,而是后面更新value。如果第一个节点不是目标key,就继续判断这个桶是不是红黑树结构:
else if (p instanceof TreeNode)
    e = ((TreeNode<K,V>)p).putTreeVal(this, tab, hash, key, value);
如果当前桶已经树化,那么就按照红黑树的方式插入或查找节点。putTreeVal会在红黑树中寻找是否存在相同key,如果存在就返回旧节点,如果不存在就插入新节点。如果当前桶既不是目标节点,也不是红黑树,那就说明它是普通链表,于是进入链表遍历:
for (int binCount = 0; ; ++binCount) {
    if ((e = p.next) == null) {
        p.next = newNode(hash, key, value, null);
        if (binCount >= TREEIFY_THRESHOLD - 1)
            treeifyBin(tab, hash);
        break;
    }
    if (e.hash == hash &&
        ((k = e.key) == key || (key != null && key.equals(k))))
        break;
    p = e;
}
这段逻辑就是沿着链表一个一个往后找。如果一直找不到相同key,并且已经走到链表尾部,就创建一个新节点挂到链表最后。插入完成后,如果链表长度已经比较长,就会尝试调用treeifyBin将链表转换成红黑树。不过这里还要注意,树化不是只看链表长度,还要看数组容量是否达到MIN_TREEIFY_CAPACITY,也就是64。如果数组容量还比较小,HashMap会优先扩容,而不是马上树化。这里我们来看下它的treeifyBin方法是如何实现的:
    /**
     * Replaces all linked nodes in bin at index for given hash unless
     * table is too small, in which case resizes instead.
     */
    final void treeifyBin(Node<K,V>[] tab, int hash) {
        int n, index; Node<K,V> e;
        if (tab == null || (n = tab.length) < MIN_TREEIFY_CAPACITY)
            resize();
        else if ((e = tab[index = (n - 1) & hash]) != null) {
            TreeNode<K,V> hd = null, tl = null;
            do {
                TreeNode<K,V> p = replacementTreeNode(e, null);
                if (tl == null)
                    hd = p;
                else {
                    p.prev = tl;
                    tl.next = p;
                }
                tl = p;
            } while ((e = e.next) != null);
            if ((tab[index] = hd) != null)
                hd.treeify(tab);
        }
    }
它干的事就是当HashMap中某个桶里的链表过长时,就尝试把这个桶中的链表节点转换成红黑树节点,从而提高查询效率;但如果当前数组容量还太小,就不会立刻树化,而是优先扩容。
一开始先判断底层数组tab是否为空,或者数组长度是否小于MIN_TREEIFY_CAPACITY,也就是64。如果数组还没有初始化,或者容量不足64,就直接调用resize()扩容。这样设计是因为数组容量较小时,链表变长很可能是因为数组太短导致冲突集中,此时扩容可以重新分散元素,比直接树化更合适。
只有当数组容量已经达到64,并且根据(n - 1) & hash找到的桶位置不为空时,才会真正进行树化操作。接下来,方法会遍历当前桶中的普通链表节点,每遍历到一个Node,就通过replacementTreeNode(e, null)将它包装成一个TreeNode节点,并使用prev和next把这些TreeNode先连接成一个双向链表。其中hd表示新的树节点链表的头节点,tl表示尾节点。
等所有普通链表节点都转换成TreeNode后,会把数组当前桶位置tab[index]指向新的头节点hd,最后调用hd.treeify(tab),真正把这些TreeNode按照红黑树规则组织起来。
如果在链表或红黑树中找到了相同key,那么e就不为null,会进入下面这段:
if (e != null) {
    V oldValue = e.value;
    if (!onlyIfAbsent || oldValue == null)
        e.value = value;
    afterNodeAccess(e);
    return oldValue;
}
这表示当前key已经存在,所以这次操作不是新增节点,而是更新旧节点的value。oldValue保存原来的值。如果onlyIfAbsent为false,就直接覆盖旧值;如果onlyIfAbsent为true,则只有旧值为null时才更新,这就是putIfAbsent()的语义。更新后返回旧值。如果前面没有找到相同key,而是成功新增了一个节点,那么会执行:
++modCount;
if (++size > threshold)
    resize();
afterNodeInsertion(evict);
return null;
modCount记录HashMap结构被修改的次数,主要用于迭代时的快速失败机制。size表示当前键值对数量,新增节点后会加一。如果size超过扩容阈值threshold,就会调用resize()进行扩容。最后的afterNodeInsertion(evict)是给LinkedHashMap这类子类预留的回调方法,普通HashMap中基本没有实际操作。
因此,putVal的核心逻辑可以概括为定位桶位置、处理哈希冲突、判断新增还是覆盖、必要时树化、必要时扩容。其余的方法,如果有兴趣,读者可自行进行解读。
总结
本文主要探讨了Java中String类的字符串常量池机制和HashMap的源码实现。在字符串常量池部分,分析了字面量赋值和new String()的区别,指出字面量会复用常量池对象,而new会创建新对象;介绍了intern()方法的作用及其在不同JDK版本中的差异。在HashMap源码分析部分,详细解读了关键常量定义、节点结构、构造函数以及核心的putVal方法实现,包括哈希计算、扩容机制、链表树化等过程,揭示了HashMap如何通过数组+链表+红黑树的结构实现高效键值存储。文章通过代码示例和图示帮助理解这些底层机制。

AtomGit 是由开放原子开源基金会联合 CSDN 等生态伙伴共同推出的新一代开源与人工智能协作平台。平台坚持“开放、中立、公益”的理念,把代码托管、模型共享、数据集托管、智能体开发体验和算力服务整合在一起,为开发者提供从开发、训练到部署的一站式体验。
更多推荐



 7
 0
- 0


 已为社区贡献14条内容

所有评论(0)